From Chunks to Graphs
Training-free multimodal late interaction for document understanding
From Chunks to Graphs is a training-free multimodal retrieval framework that complements chunk- and page-based evidence selection with structure-aware subgraph retrieval over document graphs. Published at ICDAR 2026.
Problem
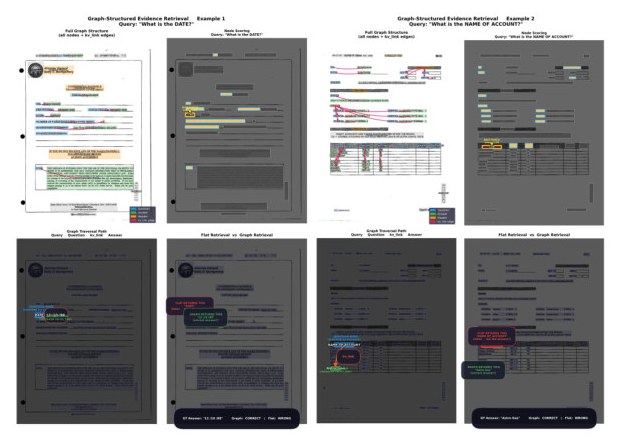
Retrieval-augmented generation over document images usually selects flat text chunks or whole pages, discarding the layout and relational structure that carries much of a document’s meaning — so the retrieved evidence is coarse and often not the exact field that answers the question.
Approach
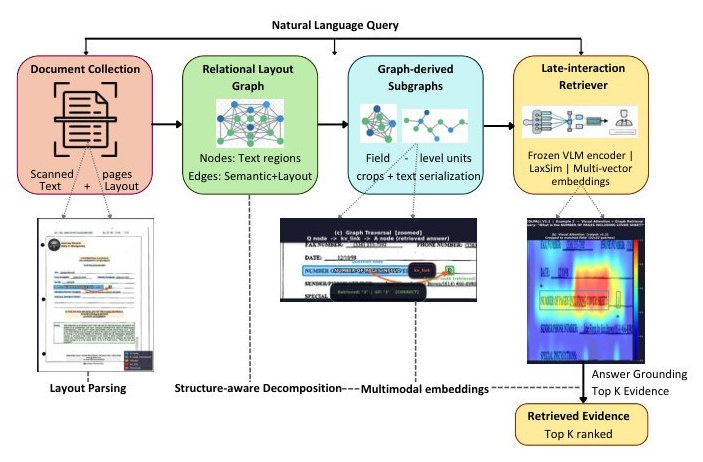
- Document graphs: each page is represented as a Doc2Graph-style graph of fields and their relations
- Multi-vector subgraph embeddings: multimodal document subgraphs are encoded into multi-vector embeddings
- Late interaction: query embeddings interact with subgraph embeddings to retrieve relationally coherent evidence at the field level
- Refines coarse page-level retrieval into precise evidence localization while keeping the efficiency of recent vision-language retrieval pipelines — no training required
Results
- Evaluated on key–value reasoning over FUNSD and XFUND
- Fusing visual relevance with structural matching improves top-1 evidence localization across multiple late-interaction backbones
- Characterizes the resulting precision–coverage trade-off, including the regimes in which fusion does not help
Publication
Lodh, A., Mazumder, S., Biswas, S., Lladós, J., Chauhan, N. S. From Chunks to Graphs: Training-Free Multimodal Late Interaction for Document Understanding. ICDAR 2026, LNCS, pp. 592–609. DOI
Work done during a research internship at the Computer Vision Center (UAB, Barcelona) with Dr. Sanket Biswas and Dr. Josep Lladós, co-advised by Dr. Nisha Singh Chauhan (NIT Delhi). The full inference pipeline will be released to support reproducibility.